See what the models make
Real outputs from the models on this page, each shown with the exact prompt that produced it. Copy a prompt, or open the model and run it yourself.
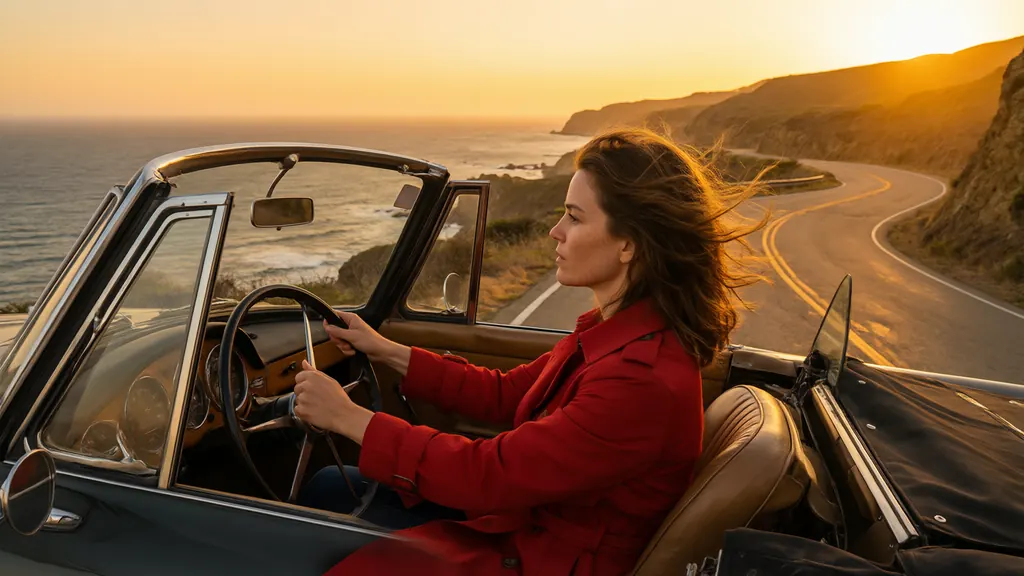
Qwen 3 UncensoredText to image
Cinematic still of a woman in her thirties in a red trench coat driving a vintage convertible along a coastal cliff road at sunset, hair blowing in the wind, warm orange light, film grain, wide anamorphic framing
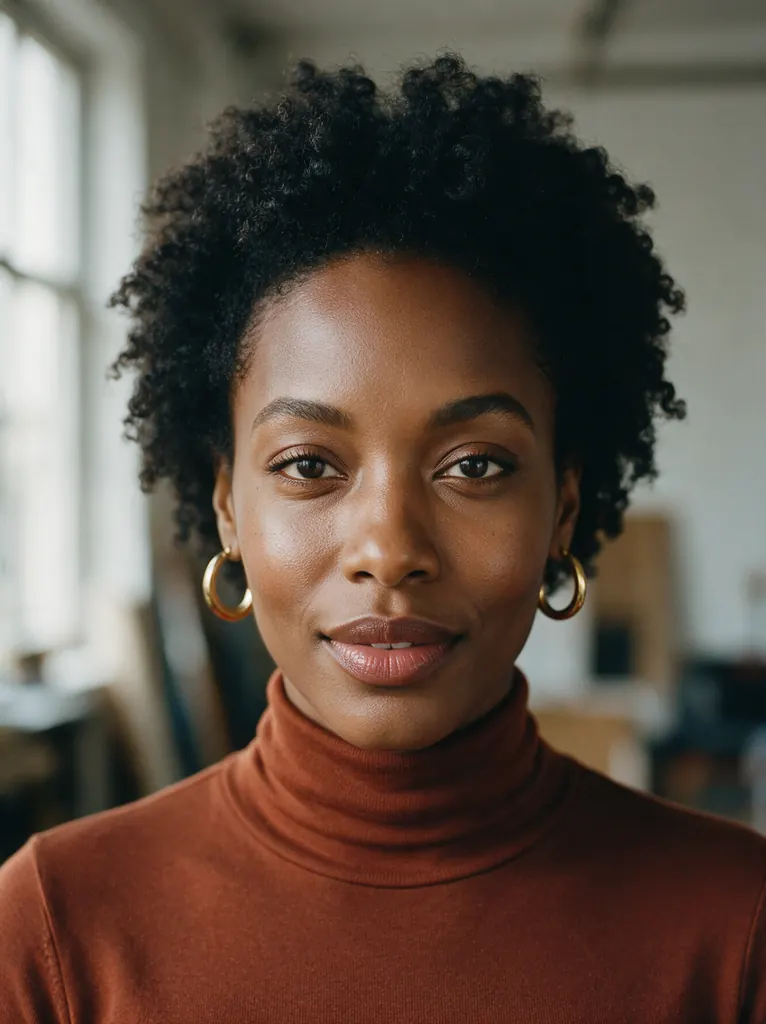
Seedream 5 Pro UncensoredText to image
Close-up editorial portrait of a confident Black woman in her early thirties with natural coily hair, gold hoop earrings and a rust-colored turtleneck, soft window light from the left, shallow depth of field, 85mm lens, warm film tones, photorealistic skin texture
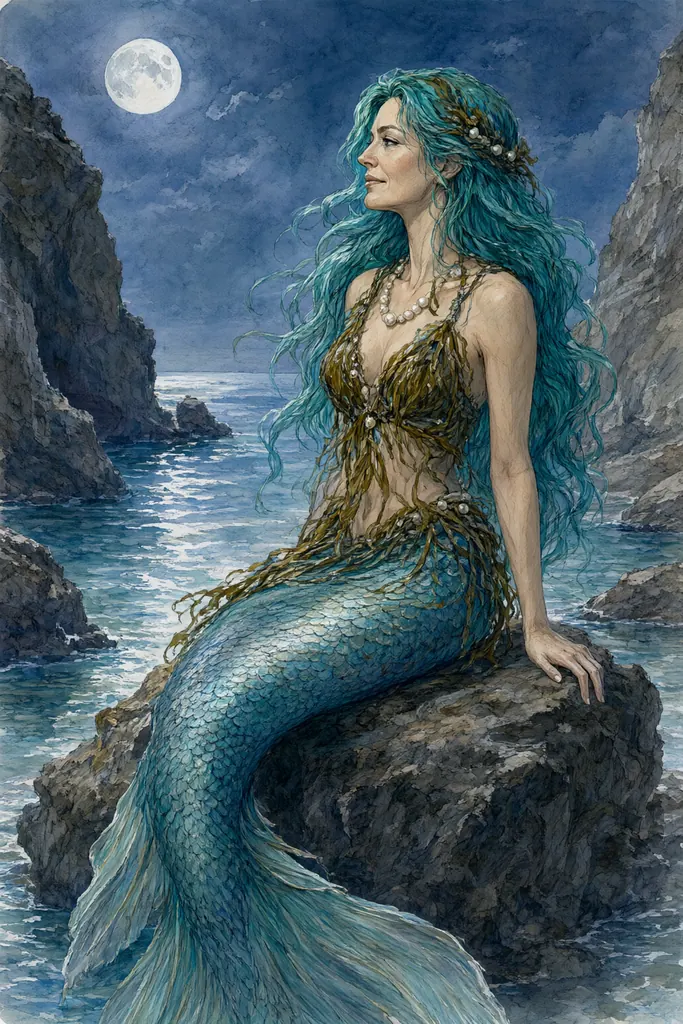
Qwen 3 Pro UncensoredText to image
Watercolor and ink illustration of a mermaid woman in her thirties wearing a top of woven seaweed and pearls, long teal hair flowing over her shoulders, sitting on a rock in a moonlit cove, shimmering scales, loose painterly washes
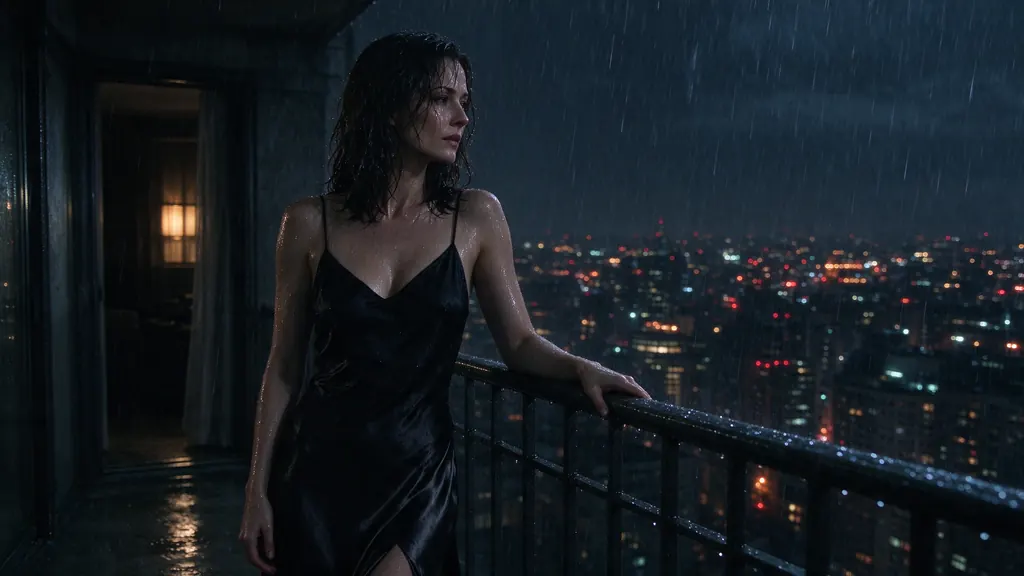
Seedream 5 Flash UncensoredText to image
Rainy night scene of a woman in her thirties in a black slip dress leaning on a balcony railing above a glowing city, rain on her skin, smoky mood, cinematic noir lighting
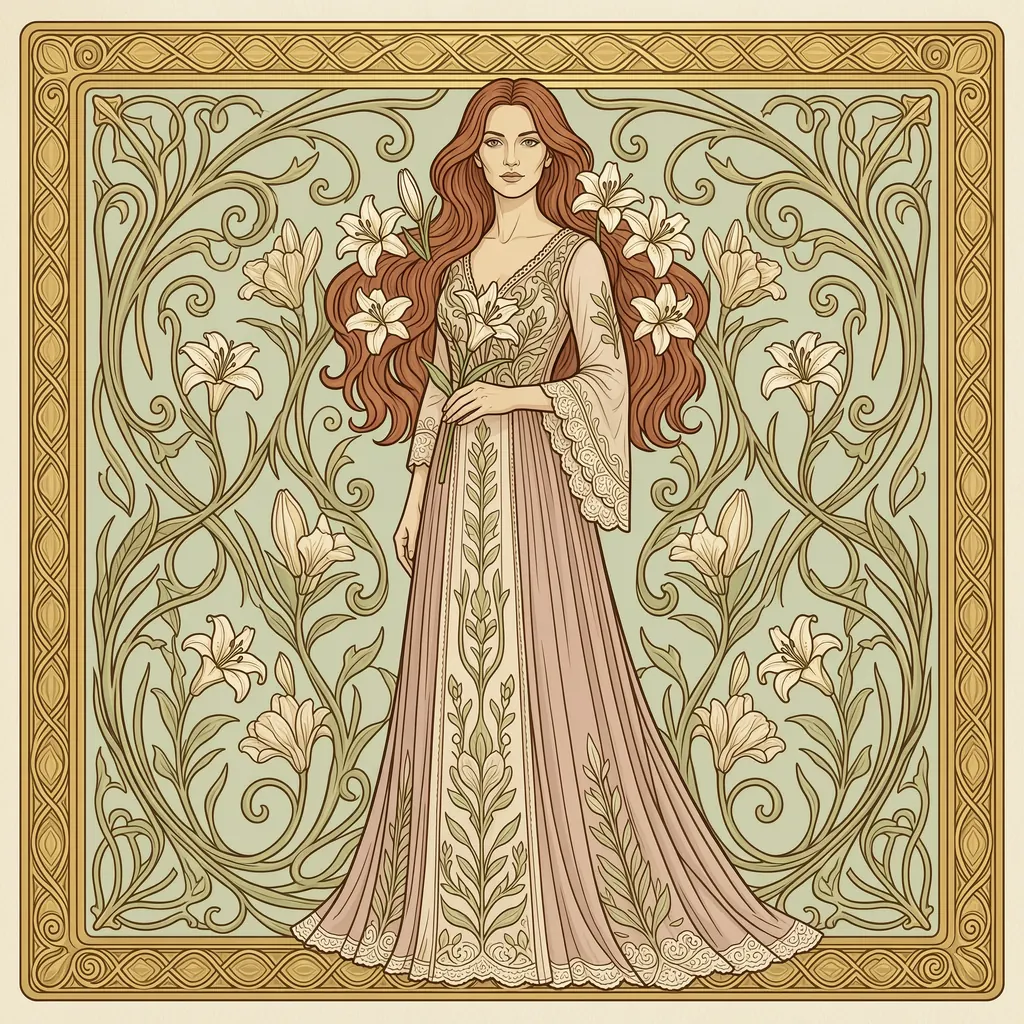
Wan 2.7 UncensoredText to image
Art nouveau illustration of an elegant woman in her thirties with flowing auburn hair intertwined with lilies, ornate golden border, muted pastel palette, decorative poster style, no text
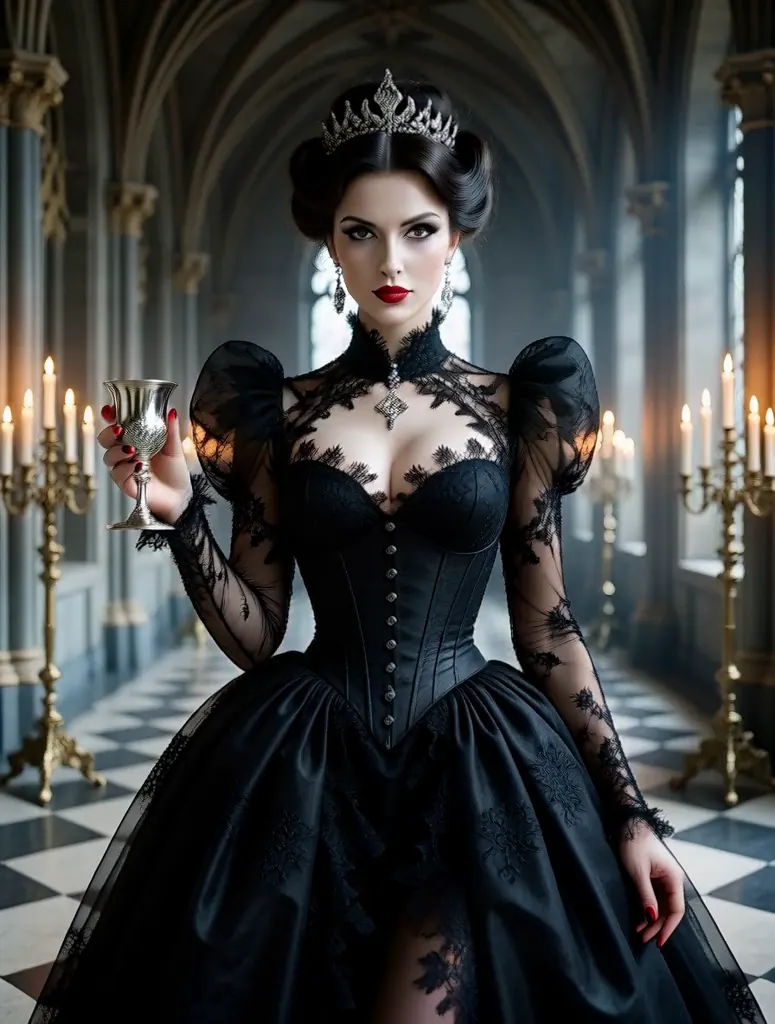
MiniMax H3 Image UncensoredText to image
Vampire countess in her thirties with porcelain skin and crimson lips, a high-collared black lace gown, holding a silver goblet in a candlelit gothic hall, dramatic chiaroscuro
What the request actually contains
A generation request carries a model id, a prompt, and the options that model accepts: a size for images; a resolution, a length and on some models an aspect ratio for video; plus the addresses of any reference pictures. That is the whole surface, listed endpoint by endpoint in the API reference. Nothing sits between your text and the render: no rewriting stage, no guidance dial, no step count. Seed and negative prompt are open on some models and not on most; the catalog endpoint and each model page say which. Where a model ships a prompt expander as a vendor setting, it is sent switched off, except on a few video models that use their own built-in thinking step.
That missing middle layer is why most prompt tricks exist elsewhere. OpenAI's image generation documentation says the model "will automatically revise your prompt for improved performance", hands the rewritten text back in a revised_prompt field, and documents no way to switch it off. Prompt-hacking is what negotiating with a rewriter looks like, and here there is nobody to negotiate with; an image generator that doesn't rewrite prompts takes that layer apart.
Keys the endpoint does not define are simply not read. Add a cfg value or a step count to the JSON and nothing happens and nothing errors. seed and negative_prompt are the exception: they are read on the models that declare them, and a model that does not declare one returns 400 rather than swallowing the field. That is worth knowing before you spend an afternoon tuning a field that was never delivered.
Move one thing, and learn your noise floor
A comparison is readable only when a single thing moved. Change the wording and the size in one run and you have two explanations for the difference and no way to separate them, so the run taught you nothing except that something happened.
There is a second source of variation and it is not yours. Omit the seed and the adapter draws a fresh one on every request, and on models that declare no seed there is no field to pin at all, so one prompt submitted twice does not come back as one picture; choosing resolution and length has the mechanism and why a bigger re-run is a fresh draw rather than an enlargement. Measure it before you read anything into an edit. Run your baseline twice, look at how far apart the two land, and treat that distance as the smallest difference a wording change has to beat. Do it on the cheapest option the model offers, since every attempt spends credits and the pricing page lists what each one charges.
You do not need a notebook for this. The prompt is stored verbatim beside the generation and comes back on every record from the generations endpoint, so your history is already the experiment log. Copy a working sentence out of it rather than retyping it: retyping is an edit you did not mean to make.
Describe the frame, not the mood
Piling up adjectives leaves the composition for the model to decide. Moody, ethereal, hyperdetailed name no subject, no placement and no light direction; they are a wish about the result rather than a description of a picture. The Hugging Face Diffusers prompting guide states the rule directly, listing subject, style and context and then telling you to "use these elements as a structured narrative, not a keyword list", because current models read language rather than match keywords. Qwen 3 is a good model to practise this on, since it is built for precisely described scenes followed as written, and the page on an AI image generator with no filter on your prompt explains why wording is the one variable you control here.
Long lists also fail in a documented way. In Attend-and-Excite (Chefer et al., SIGGRAPH 2023) the authors assess "catastrophic neglect, where the model fails to generate one or more of the subjects from the input prompt", and report that it also "fails to correctly bind attributes (e.g., colors) to their corresponding subjects". That starts at two subjects and two colours, not at ten.
So write decisions. What is in the frame and where it sits, where the light comes from and how hard it is, what the lens does to the background. Each one is checkable against the render: you can see whether the light came from the left. You cannot see whether it was ethereal, so that word can never tell you your edit worked.
A negative prompt is not on every model
Reaching for a negative prompt is muscle memory from local pipelines, and it was never a way of writing. It is a separate argument to the sampling loop. The Diffusers reference defines negative_prompt as "the prompt or prompts not to guide the image generation" and notes it is "ignored when not using guidance", so the field exists because there is a guidance step with an unconditional branch to steer away from.
A negative prompt exists here only on the models that declare one, and everywhere else anything you type is description. "No watermark, no text" is a sentence that names a watermark and text. State the positive instead: rather than no hat, say what is on the head; rather than not blurry, say what is sharp and how quickly the background falls away.
When an unwanted element survives several attempts, stop re-rolling. Hand the frame you have to an editing model as a reference and describe the change against it, which is a shorter argument and a different kind of request. The catalog marks which models read references, and keeping a character consistent covers what an attachment holds that a sentence cannot.
What wording cannot buy
Video wants more from the same field. A clip is rendered as one take, so your sentence has to carry motion and camera as well as the frame, and the camera is the part people leave out: omitting it picks one for you. From a still to a video is that handoff, and calling the API from your code is the same loop driven from a script.
What no phrasing buys is a way past the rules. The automatic check reads the prompt for one thing, sexual content involving a minor; a request it catches is refused before the run starts, so it costs nothing; it does not read your tone, and rephrasing does not take a request outside what the terms prohibit. Using a real person without their consent is forbidden by the terms, famous or not; no check detects it, and rewording does not change that either. What is allowed and what is blocked sets out the line.